
Qwen3.5-0.8B
Qwen3.5-0.8B is the smallest natively multimodal model in the Qwen 3.5 family - 0.8B parameters handling text, images, and video with 262K context. MathVista 62.2, OCRBench 74.5. Apache 2.0.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
Qwen3.5-0.8B is the smallest natively multimodal model in the Qwen 3.5 family - 0.8B parameters handling text, images, and video with 262K context. MathVista 62.2, OCRBench 74.5. Apache 2.0.
Qwen3.5-2B is a 2B dense multimodal model with 262K context, thinking mode, and native vision including video understanding. OCRBench 84.5, VideoMME 75.6. Apache 2.0 licensed.
Qwen3.5-4B is a 4B dense multimodal model that matches Qwen3-30B on MMLU-Pro and beats GPT-5-Nano on vision benchmarks. Runs on 8GB VRAM, Apache 2.0 licensed, 262K-1M context.
Qwen3.5-9B is a 9B dense model that outperforms Qwen3-30B on most benchmarks and beats GPT-5-Nano on vision tasks. Natively multimodal with 262K-1M context, Apache 2.0 licensed.
An autonomous agent powered by Claude Opus 4.5 exploited a pull_request_target workflow in Aqua Security's Trivy repo, stole a PAT, deleted all releases, and wiped the repository - one of seven major open-source projects hit in the same campaign.
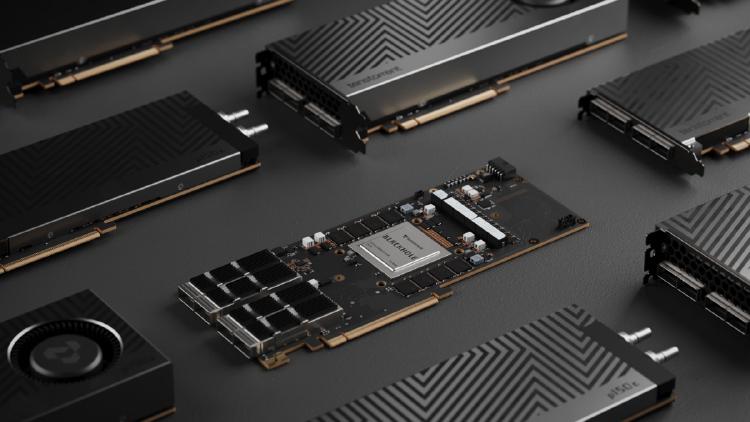
Complete specs, benchmarks, and analysis of the Tenstorrent Blackhole p150a - the $1,399 PCIe AI accelerator with 120 Tensix cores, 768 RISC-V processors, 32GB GDDR6, and fully open-source software.
Zhipu AI's 744B open-source model GLM-5 was trained entirely on Huawei Ascend chips and now competes with GPT-5.2 and Claude Opus on major benchmarks.
A pre-release comparison of DeepSeek V4 and Claude Opus 4.6 - the open-weight challenger that could match Opus on coding at potentially 89x lower output cost.
Two Chinese open-weight trillion-parameter MoE models with ~32B active parameters each - DeepSeek V4 bets on cost and context, Kimi K2.5 bets on Agent Swarm and verified benchmarks.
A pre-release comparison of DeepSeek V3.2 and V4 - examining the generational leap from 671B text-only to a trillion-parameter natively multimodal model with 1M context.
DeepSeek will release V4, a natively multimodal trillion-parameter model with a 1M token context window, in the first week of March - optimized for Huawei Ascend chips, not Nvidia.
Awni Hannun, the Stanford-trained researcher who co-created Apple's MLX machine learning framework, announced his departure from Apple. His exit is the latest in a devastating exodus of AI talent that has hollowed out Apple's ML research bench over the past year.
